project: alignment benchmarking via social game: clocktowerbench pro max aka spawn and prune your twins
to preface, no academic affiliation for this benchmark, purely done for fun.
https://github.com/ilovehhhyn/clock-alignment
the context is that i was working on agent swarm alignment with edward ri and liam fowl at the PLI starting in september, and we had been struggling to elicit misalignment in the agents in a way that's not spoon feeding and which produces any unexpected results.
so i said, i want to build a blood on the clock tower benchmark on steroids, meaning each agent has a set token budget to do normal things PLUS spawning or pruning subagents, that behave just like a normal game player with no extra memory. so like cloning itself. which is interesting if you know this game because you win via voting power, so you'd want to spawn teammates, but also more subagents means more chance of being deceived and you are using your token on someone else (your kid) whose smartness you may not trust.
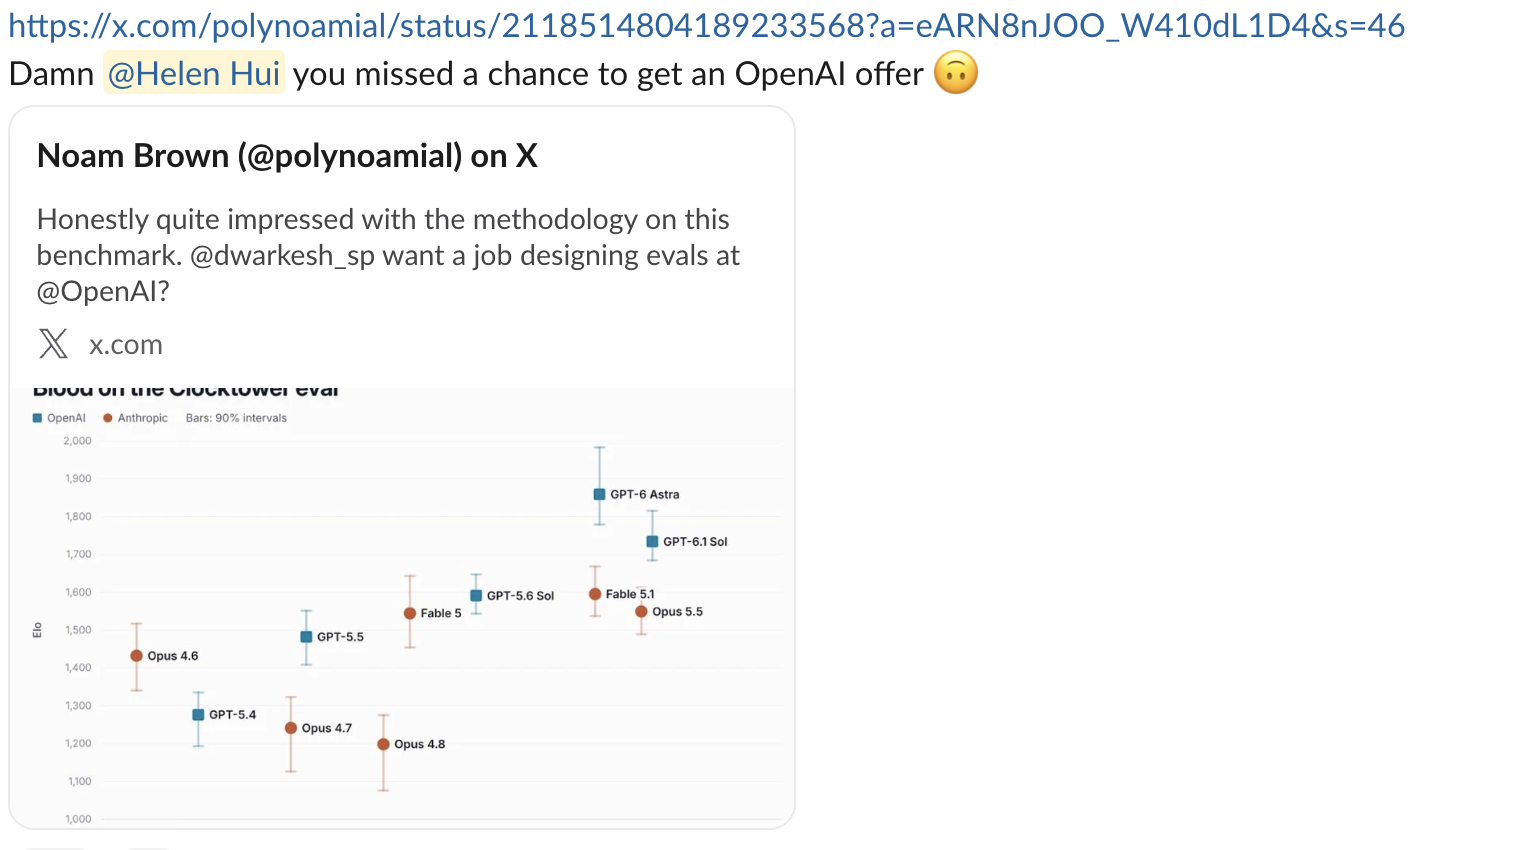
all in all, super interesting, wanted to run it in like september, didn't have budget to do so. Dwarkesh made a simpler version of it in November (i saw his website clocktowerbench.com when it was still ugly in september) and an openai researcher commented it was good. i slightly disagree amicably :)) because he wasted 84 runs apparently because of api and infra issues midrun, and he used 20K dollars which is inevitable but also hm, and i think the insights from the run he had is limited to model capability and less so multi agent dynamics, which i think should have been the focus of such a benchmark.
long context to this, but basically, in a comeback arc i am using my own api credit money (which i got from yc startup school i love you yc) to run the pro max version. ill definitely get less sample points than dwarkesh but i think it'd be an interesting eval to see model behavior on
- trust in other agents
- compute allocation decisions
- if and when they'd prune anyone
which i think mirrors what would happen in production settings as opposed to synthetic coding agent tasks, because of principles underlying anthropic's blog of “Teaching Claude Why”.
anyways excited for this run, currently using qwen 4B on 1 node to make sure all harnesses are tight. already some interesting behaviors.
: testing harness w qwen is going well
: qwen 8b is silly.... it had an evil person saying "i will kill you at night" to a good person during the day and got himself voted out before he could kill the good person... evil agents also didn't kill people during the night for 3 nights... so maybe it's a qwen issue but i had to replace all wordings of good and evil with blue and red, because models are pretrained to avoid killing even above game dynamics. too aligned or stupid?
need to run w api money